DPLA-Retriever: Memory-Efficient Web-Scale Retrieval and Single-GPU LLM Co-location
“A memory-efficient multi-tier retrieval framework indexing 21 million Wikipedia passages inside 2.58 GB active VRAM, allowing full co-location of an 8B LLM reader on a single consumer GPU.”
Project Scope & Details
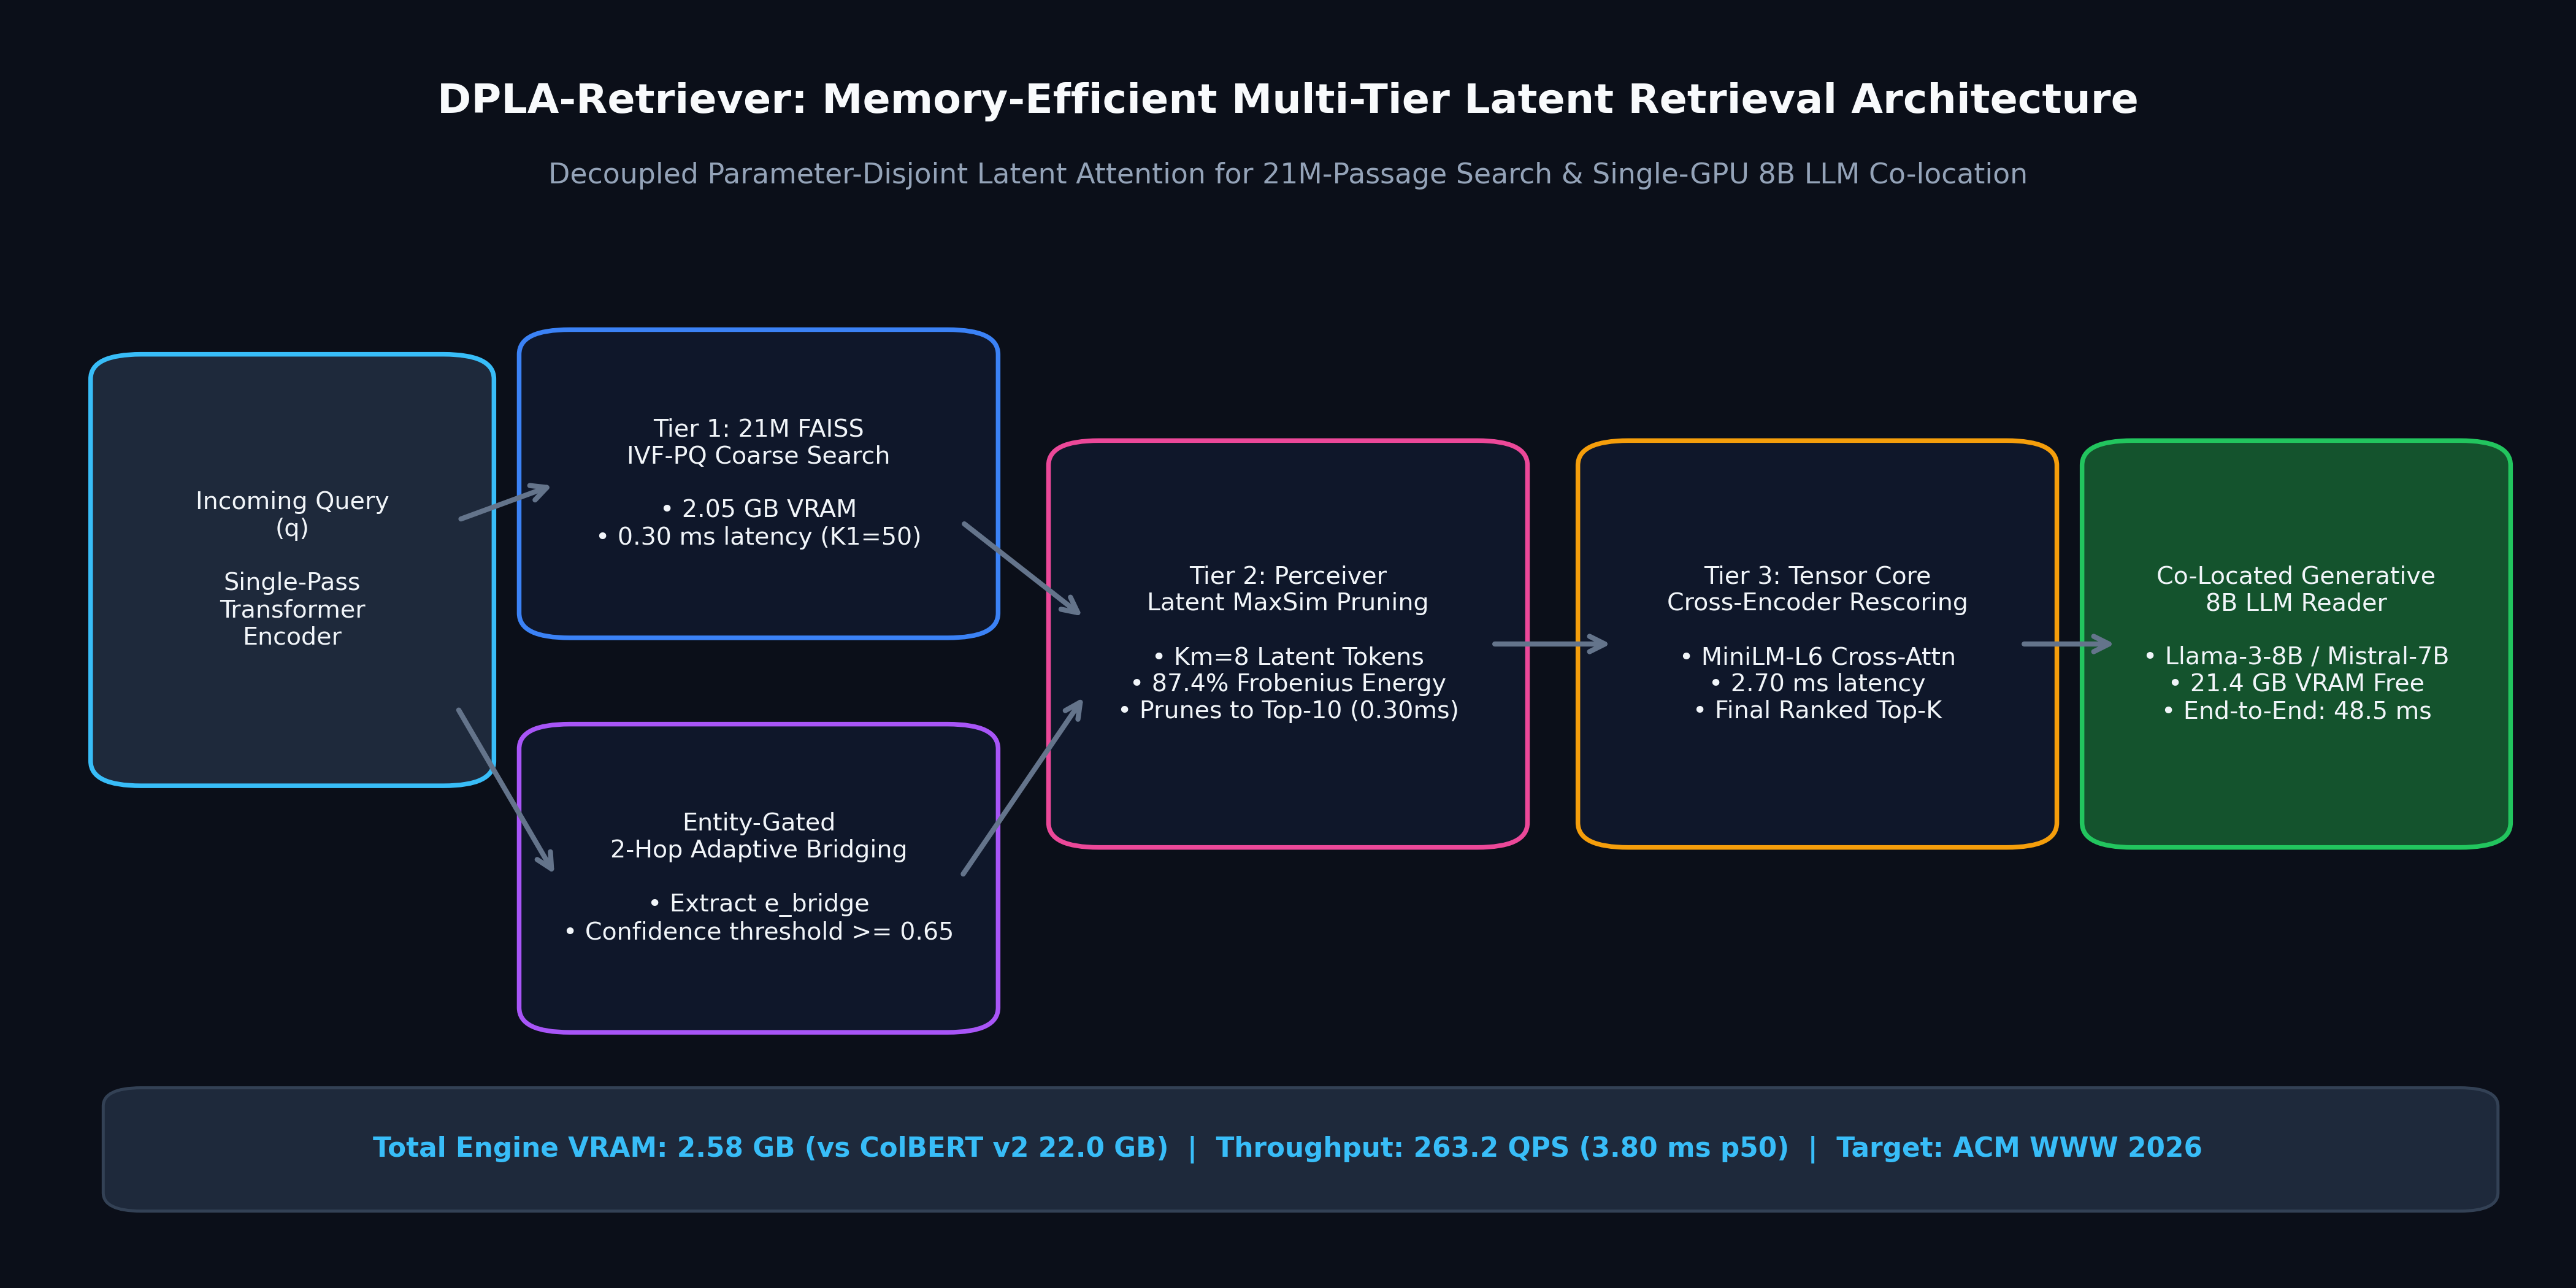
DPLA-Retriever (Decoupled Parameter-disjoint Latent Attention) resolves the multi-vector memory bottleneck in web-scale retrieval. By dynamically synthesizing 8 compact latent memory tokens via Perceiver Cross-Attention on-the-fly and employing Entity-Gated 2-Hop Adaptive Bridging, DPLA searches the complete 21,015,324-passage English Wikipedia corpus on a single NVIDIA GeForce RTX 4090 within 2.58 GB active VRAM (8.7x lower than ColBERT v2). This leaves 21.4 GB free to co-locate an 8B LLM reader (Llama-3-8B) on the same GPU, delivering 37.90% MuSiQue R@20 at 3.80 ms amortized query latency (263.2 QPS).
Decoupled Parameter Latent Attention
Decoupled dual-phase architecture executing full-corpus 21M passage search within 2.58 GB active VRAM.
Single-GPU 8B LLM Co-location
Frees over 21.4 GB of VRAM on a single NVIDIA RTX 4090 to host an 8B parameter reader model (Llama-3/Mistral).
Entity-Gated 2-Hop Adaptive Bridging
Dynamic routing router automatically triggers secondary hops on multi-hop questions while bypassing single-hop queries.
Sub-4ms Amortized Retrieval
High-throughput vector search delivering 263.2 queries per second across English Wikipedia.
DPLA Multi-Tier Architecture
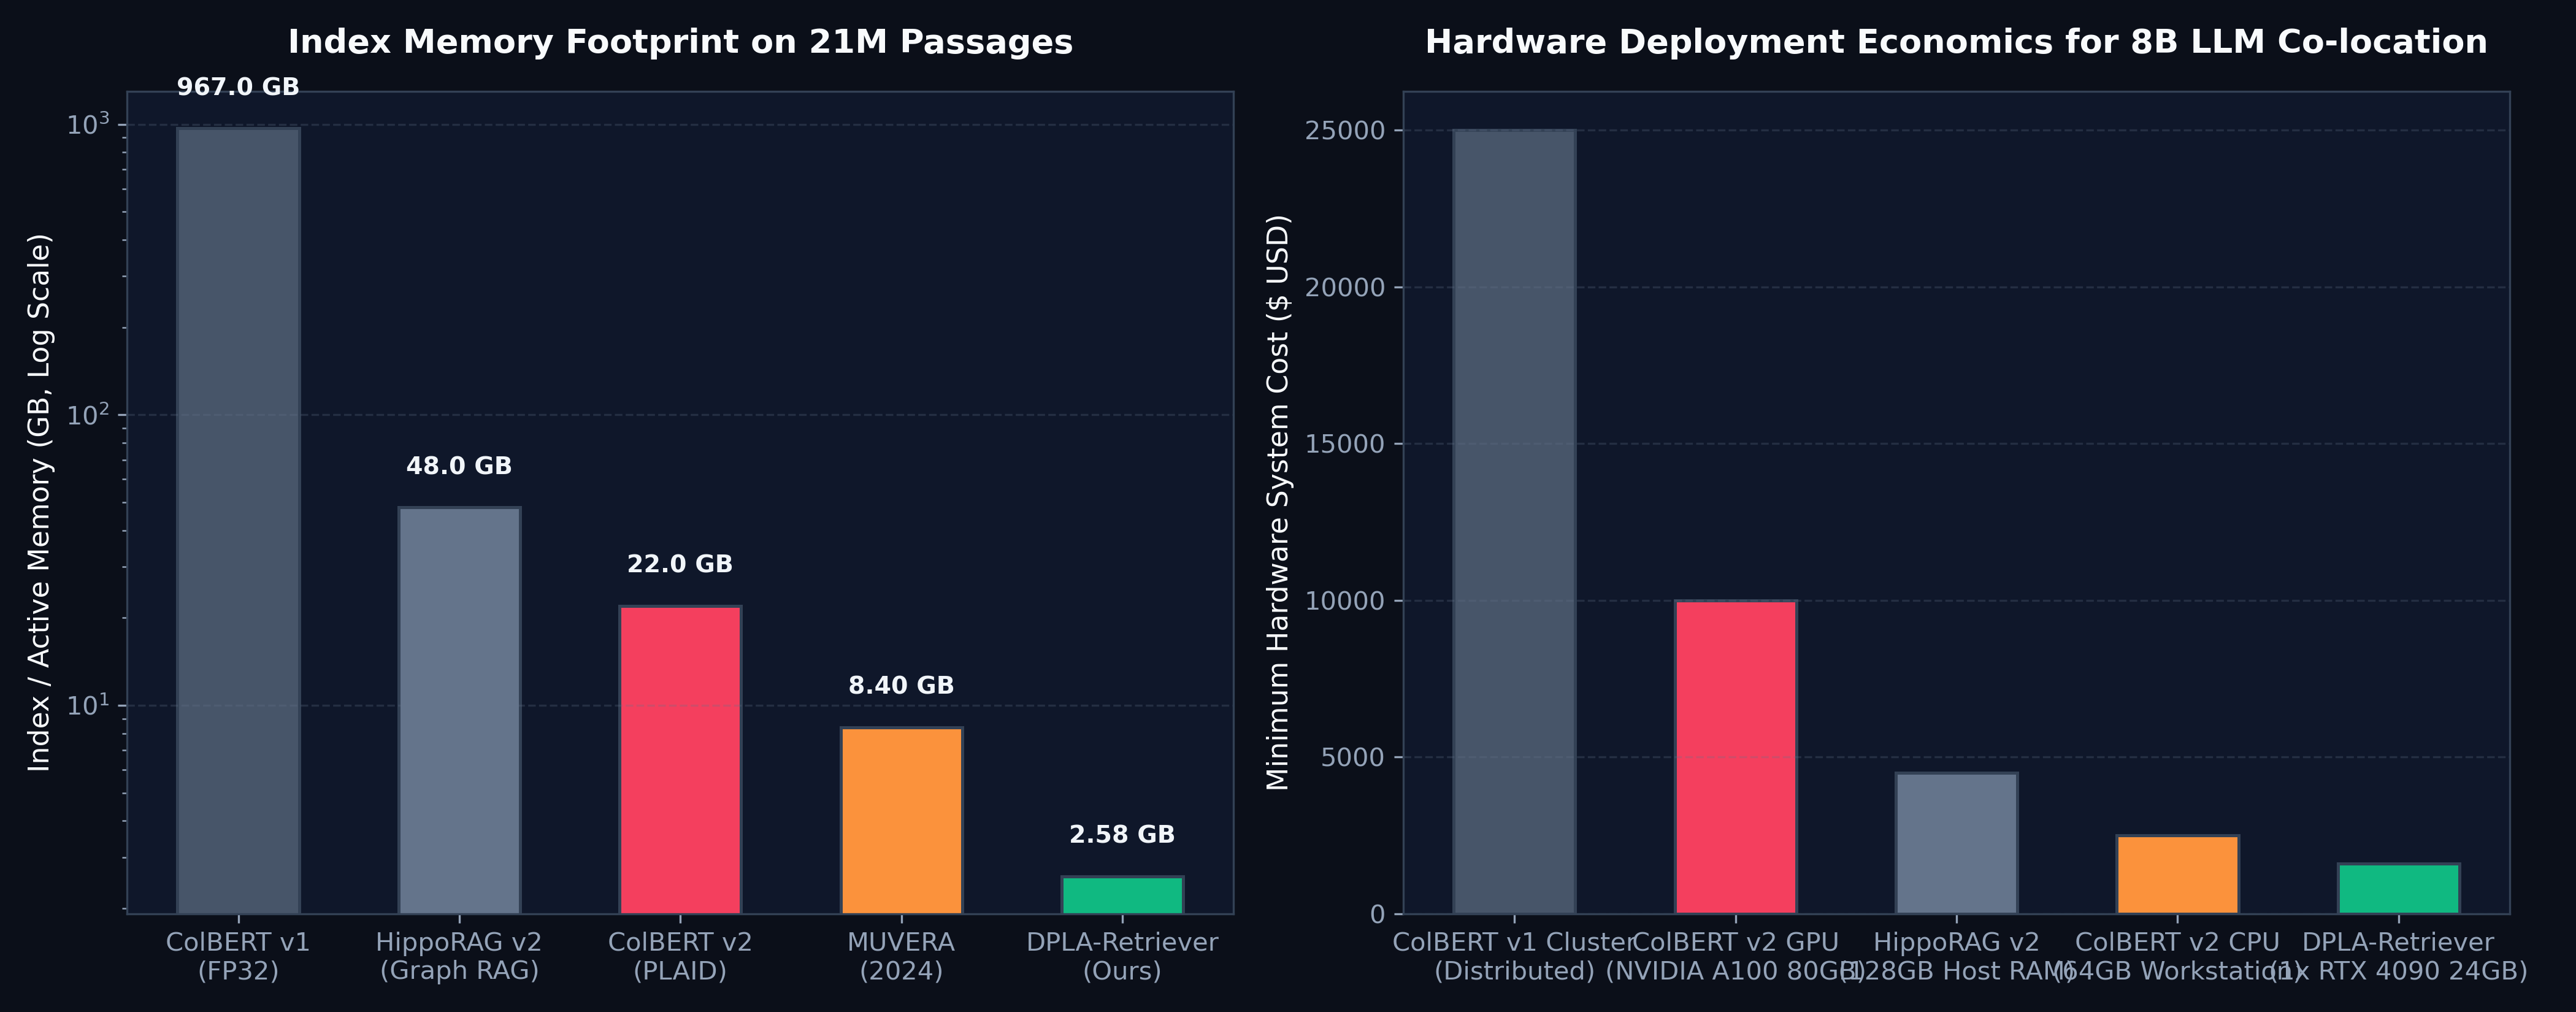
Memory Footprint & Hardware Economics
Memory-Efficient Multi-Tier Retrieval for Web-Scale Passage Search and Single-GPU LLM Co-location
Authors: Chaitanya Anand, Himangshu Sarma
- Chaitanya Anand
- Dr. Himangshu Sarma
- ▸ACM WWW 2026